Galerie de prompts IA OpenZhenZhen · gpt-image-2.5 · image
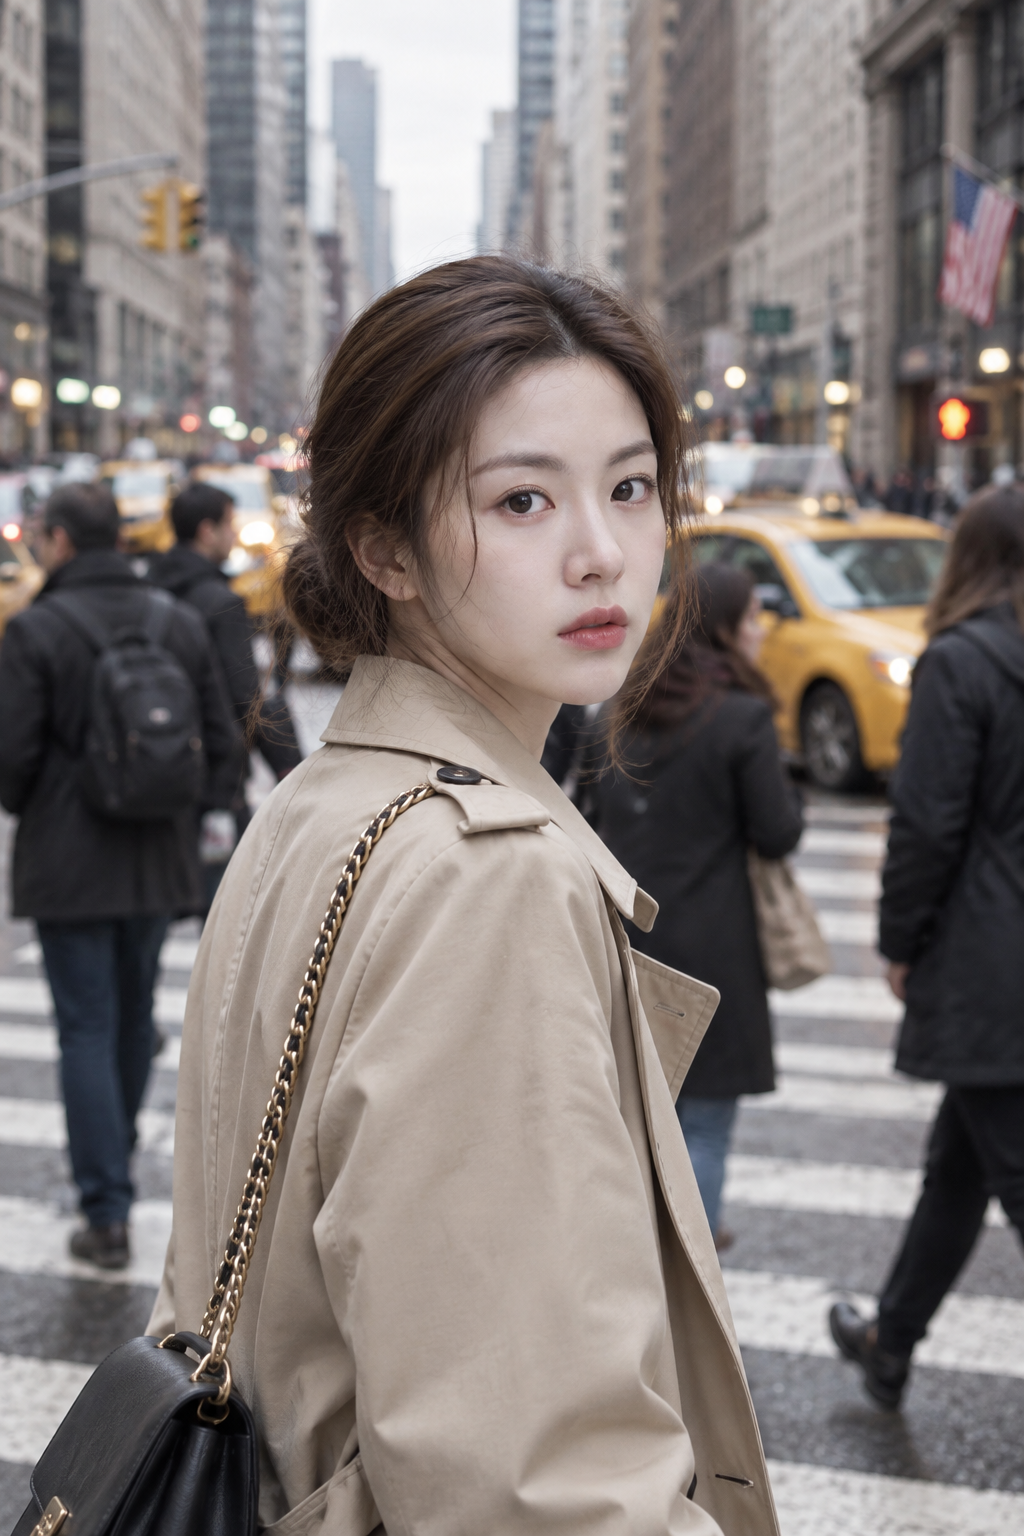
Regard documentaire d'une femme adulte en trench-coat à une intersection urbaine
Documentary Glance Back of an Adult Woman in a Trench Coat at a City Intersection
Regard documentaire d'une femme adulte en trench-coat à une intersection urbaine — découvrez cette création avec gpt-image-2.5 sur OpenZhenZhen, son prompt original et un exemple de génération à réutiliser.
Prompt
Prompt chinois
创作一张具有电影纪录片真实感的写实街头抓拍照片。一位无固定身份的成年女性站在繁忙城市人行横道上,在转身过程中被自然捕捉,直视镜头,表情平静、内省且略带疏离。她的头发松散向后扎起,柔软发丝围绕脸部;穿米色风衣,搭配细金链单肩包。背景包含移动中的行人、黄色出租车和高大城市建筑,背景细微运动暗示真实城市生活。采用非摆拍的腰部以上抓拍构图,记录自发转身瞬间;主体超清晰,背景有自然运动模糊,浅景深和柔和电影感散景。使用自然阴天日光、柔和中性色调与真实生活化城市氛围。85mm镜头视角,街头摄影与纪录片风格写实主义,呈现高细节、照片级真实纹理和极少且自然的后期处理。主体保持自然比例和真实肤色。画幅为2:3竖向单张图。不要摆拍感、时尚大片感、影棚灯光、过饱和色彩、过度修图、卡通、动漫、主体模糊、文字、标识或水印。
Prompt anglais
Create a realistic street photograph with cinematic documentary realism. A generic adult woman with no fixed identity stands at a busy urban crosswalk, naturally captured mid-turn as she looks directly toward the camera with a calm, introspective, slightly distant expression. Her hair is loosely tied back with soft strands framing her face; she wears a beige trench coat and a thin gold-chain shoulder bag. The background includes pedestrians in motion, yellow taxis, and tall city buildings, with subtle background movement suggesting lived-in city life. Use waist-up candid framing of an unposed spontaneous turning moment, keeping the subject ultra-sharp with natural background motion blur, shallow depth of field, and soft cinematic bokeh. Use natural overcast daylight, muted neutral tones, and an authentic urban atmosphere. Use an 85mm lens perspective, street-photography and documentary-style realism, high detail, photorealistic textures, and minimal natural post-processing. Preserve natural proportions and true-to-life skin tones. Output a single vertical image in a 2:3 aspect ratio. No posed look, fashion-editorial styling, studio lighting, oversaturated colors, heavy retouching, cartoon, anime, blurry subject, visible text, logos, or watermarks.
Découvrir plus de prompts image et vidéo · Générer des images · Générer des vidéos · Créer sur le canevas IA
Œuvres associées
- Portrait xianxia des années 90 en hanfu vert émeraude, tons froids
Portrait xianxia des années 90 en hanfu vert émeraude, tons froids — découvrez cette création avec gpt-image-2.5 sur OpenZhenZhen, son prompt original et un exemple de génération à réutiliser.
- Affiche de collection ultra-détaillée de star en BD 3D
Affiche de collection ultra-détaillée de star en BD 3D — découvrez cette création avec gpt-image-2.5 sur OpenZhenZhen, son prompt original et un exemple de génération à réutiliser.
- Prompts de design d'affiche de course rétro
Prompts de design d'affiche de course rétro — découvrez cette création avec gpt-image-2.5 sur OpenZhenZhen, son prompt original et un exemple de génération à réutiliser.
- Instruction de génération de stickers de chat pour personnages chibi
Instruction de génération de stickers de chat pour personnages chibi — découvrez cette création avec gpt-image-2.5 sur OpenZhenZhen, son prompt original et un exemple de génération à réutiliser.
- Affiche encyclopédique pour enfants : À la découverte des abeilles
Affiche encyclopédique pour enfants : À la découverte des abeilles — découvrez cette création avec gpt-image-2.5 sur OpenZhenZhen, son prompt original et un exemple de génération à réutiliser.
- Photographie de portrait en collage de blocs de couleur mode
Photographie de portrait en collage de blocs de couleur mode — découvrez cette création avec gpt-image-2.5 sur OpenZhenZhen, son prompt original et un exemple de génération à réutiliser.